Proxy HTML API: Fetch Web Pages Without Element Mapping
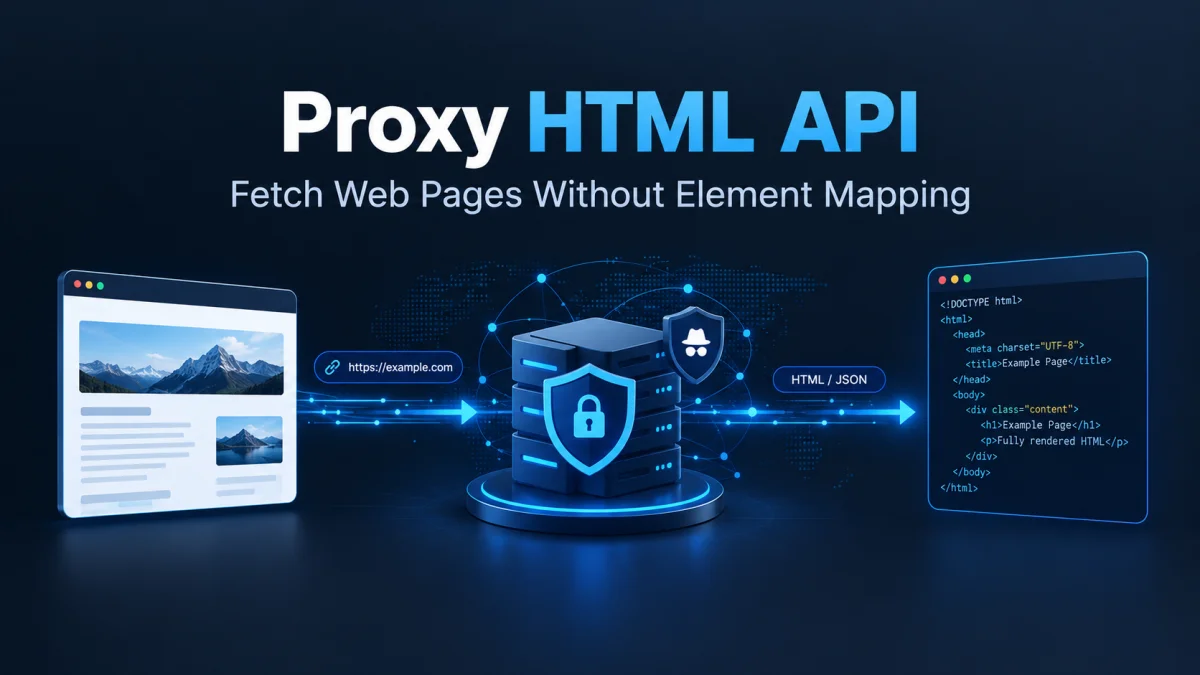
Need raw page HTML through Gluedly stealth proxies without element mapping? POST /api/v1/proxy returns plain HTML or JSON with JS rendering, bot bypass, and success-only billing.
 Gluedly
Product updates, guides, and insights.
Need raw page HTML through Gluedly stealth proxies without element mapping? POST /api/v1/proxy returns plain HTML or JSON with JS rendering, bot bypass, and success-only billing.
Gluedly now hosts remote MCP with OAuth 2.1. When Cursor, Claude, Codex, or any MCP client hits a 401, it opens Gluedly login, you approve access, and we mint a fresh MCP API key — no copy-paste, no stale tokens.
What changed?
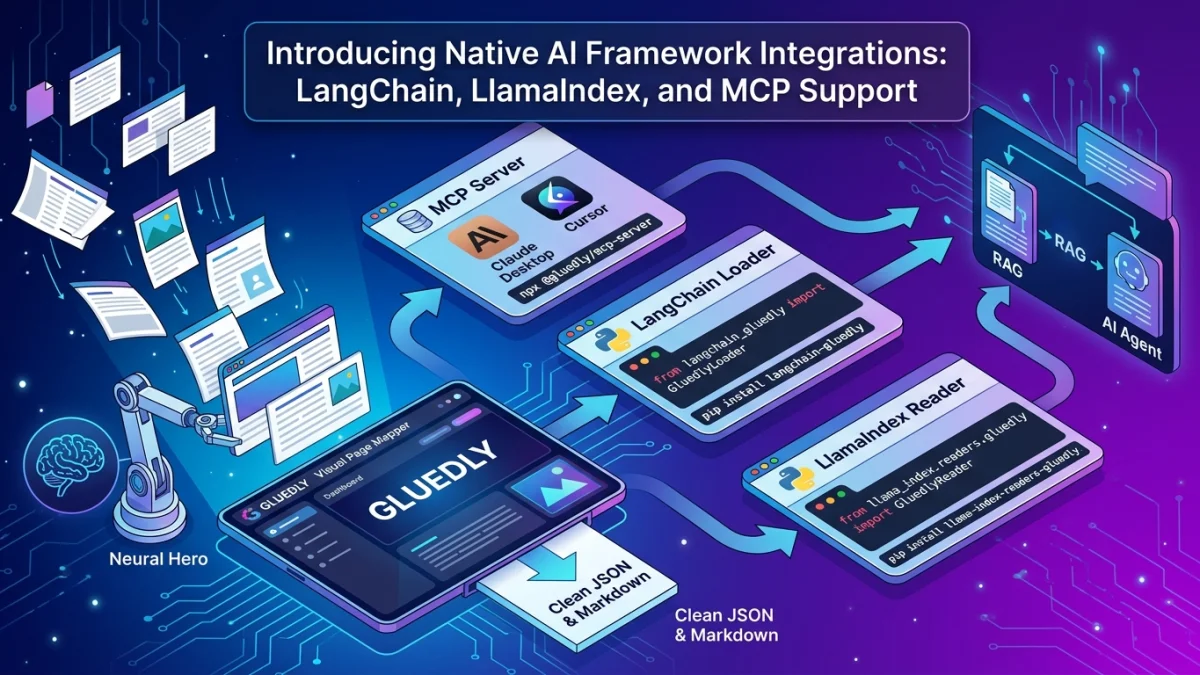
/mcp instead of only local stdio.@gluedly/mcp-server when you want a local bridge.We are excited to announce a major milestone in Gluedly’s evolution as an LLM-ready web data extraction platform: official package releases across PyPI and npm!
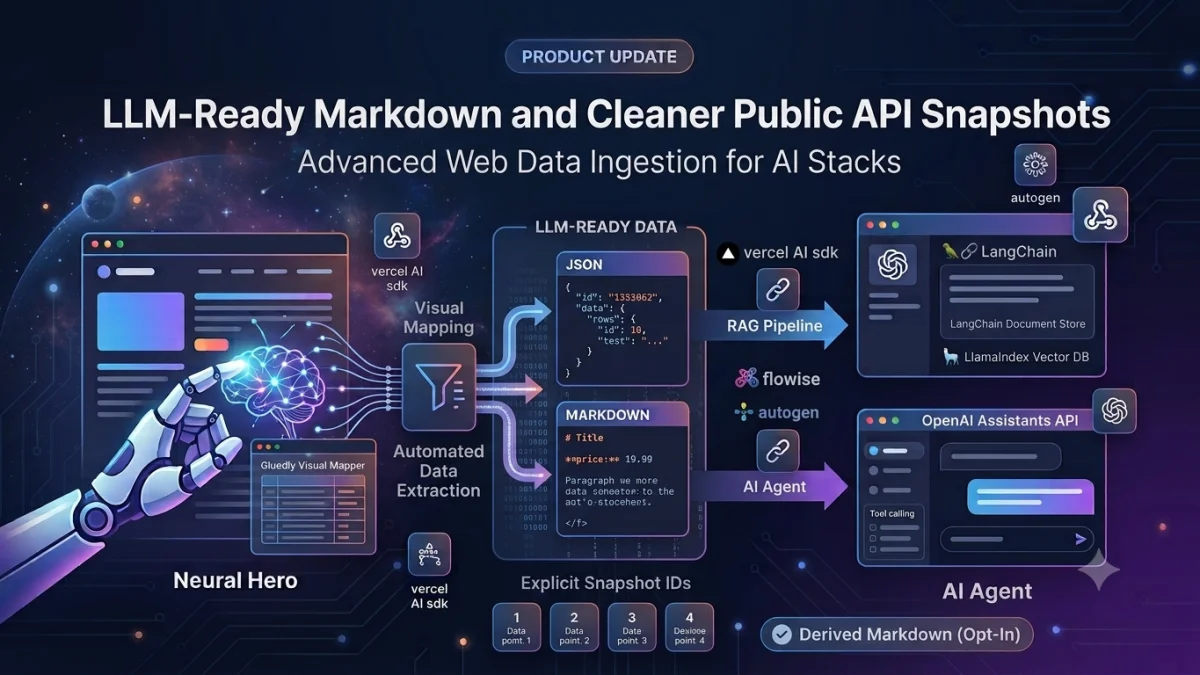
Easily pull prompt-ready Markdown directly from your scrape rows, plus enjoy explicit snapshot IDs on the public API for effortless list → detail routing in RAG and agent pipelines.
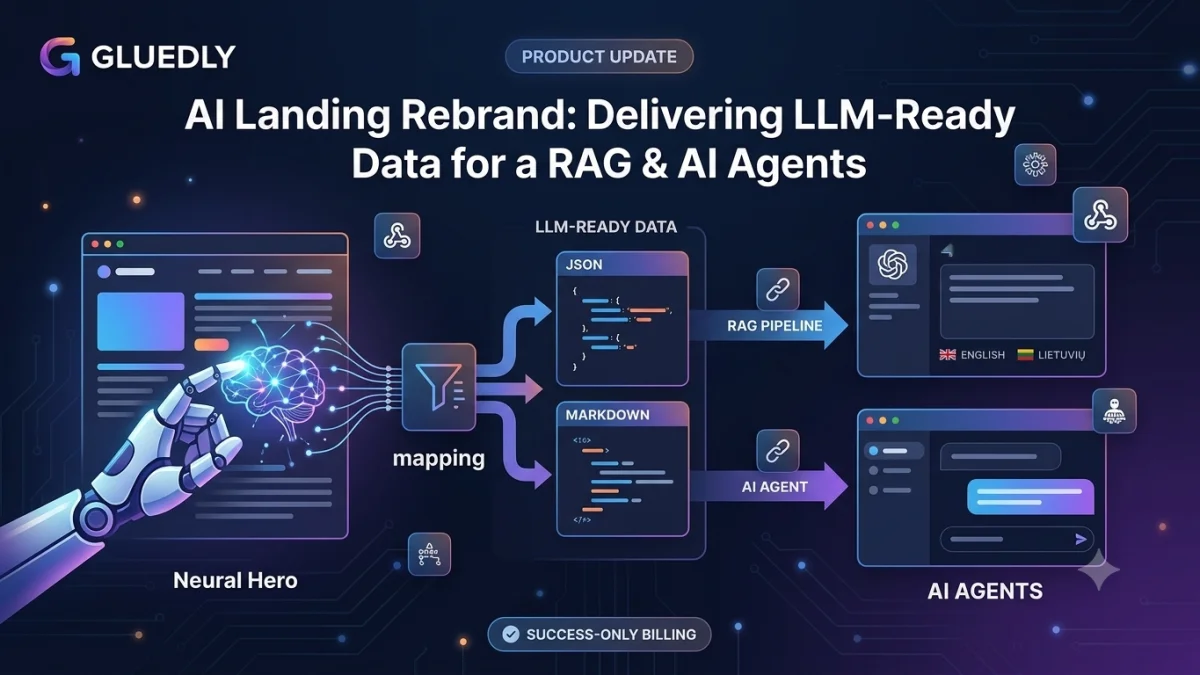
We rebuilt Gluedly’s homepage specifically for modern AI teams—featuring a dark neural hero, RAG-focused extraction capabilities, direct framework integration guides, and a complete Lithuanian localization pass.
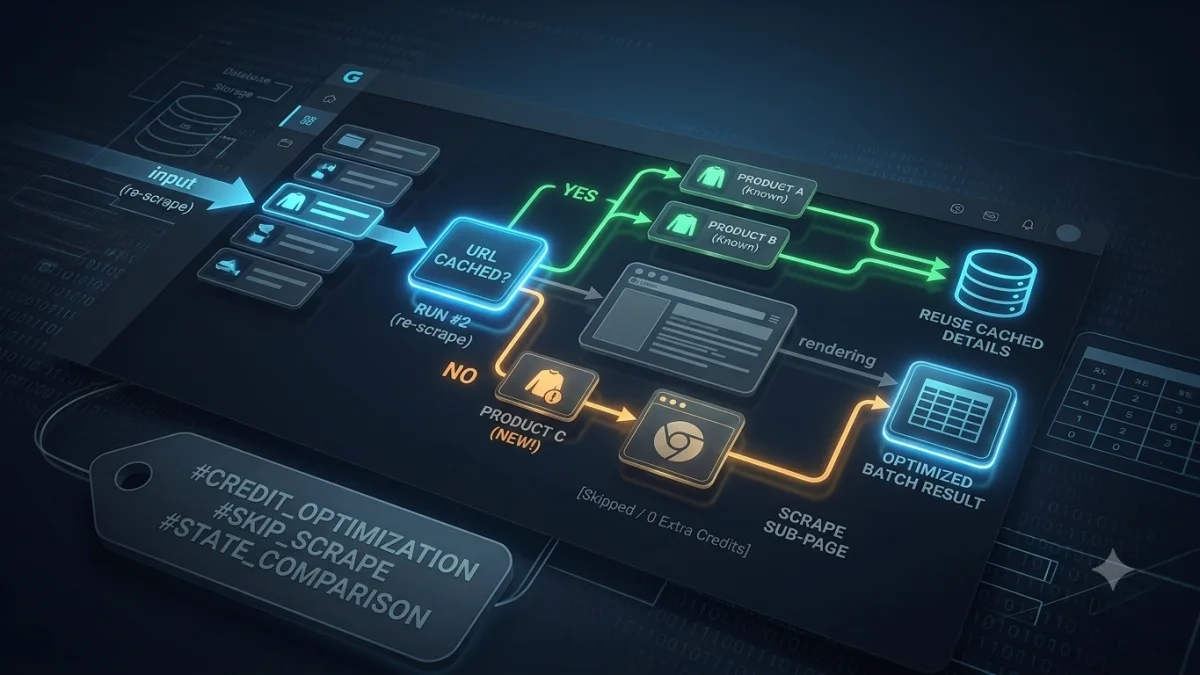
Stop burning credits re-scraping static detail pages. On re-runs, Gluedly now automatically reuses details from your last successful scrape for known URLs, only opening sub-pages for brand-new products.
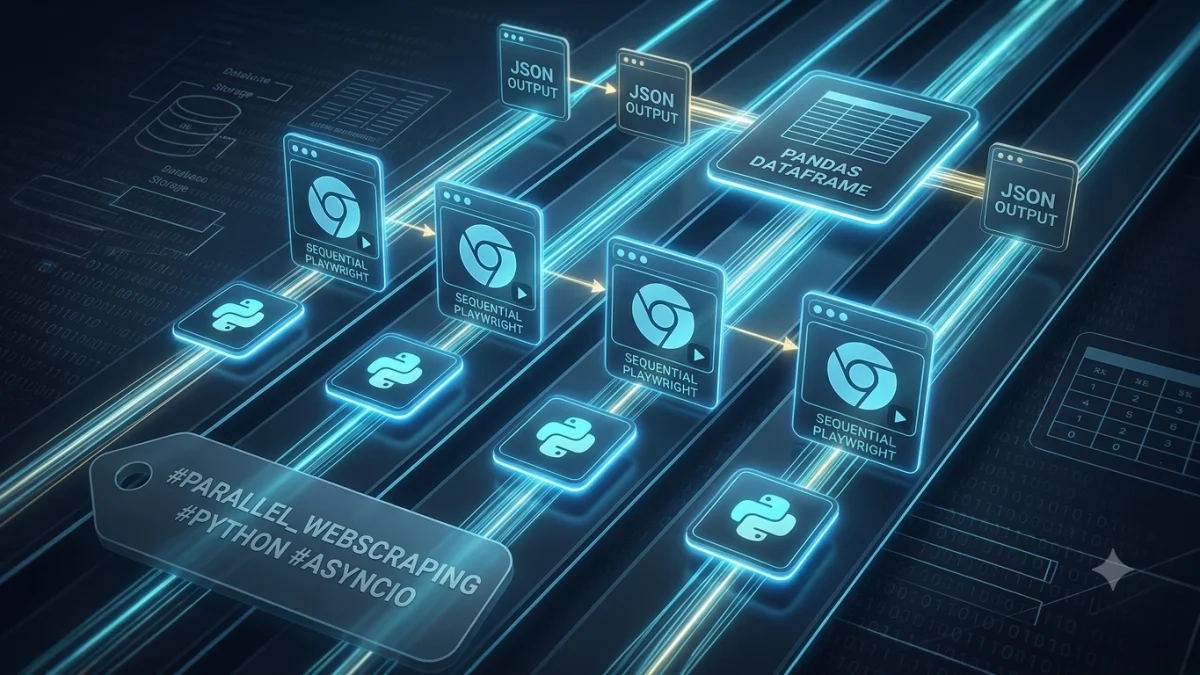
Stop throttling your scraping tasks in slow sequential loops. Learn how to implement parallel webscraping in Python by offloading execution to Gluedly's managed lanes.
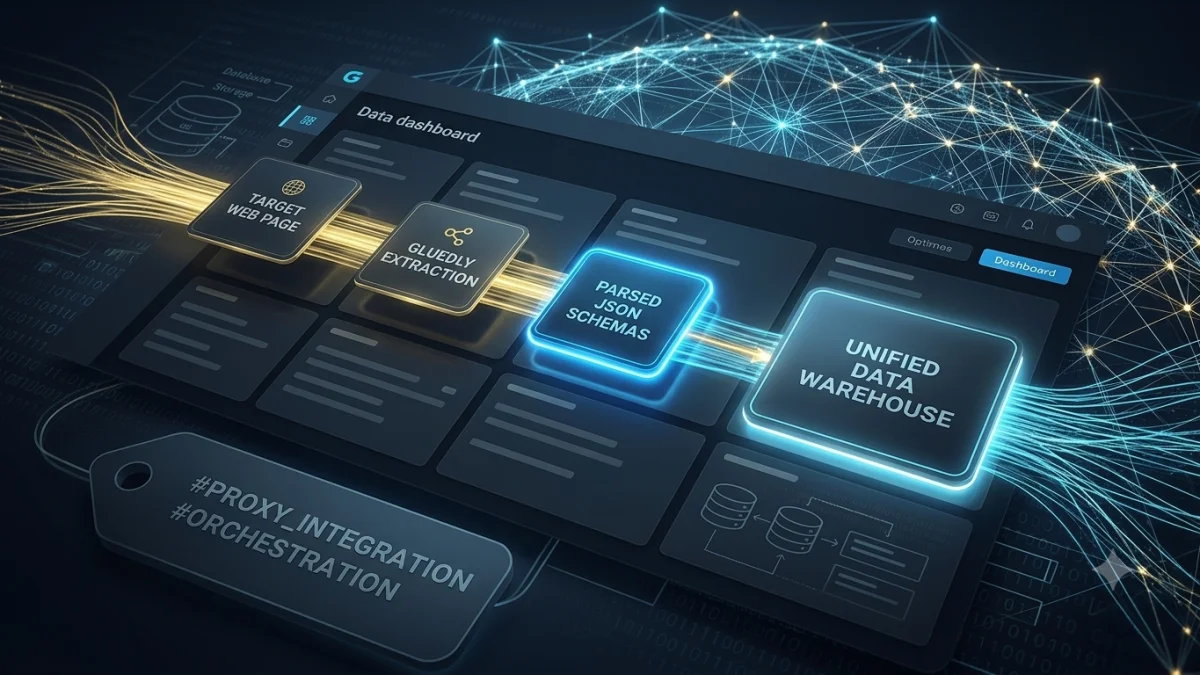
Using Decodo for high-quality residential IPs? Learn how adding Gluedly to your stack automates the parsing, scheduling, and webhook delivery without messy local script maintenance.
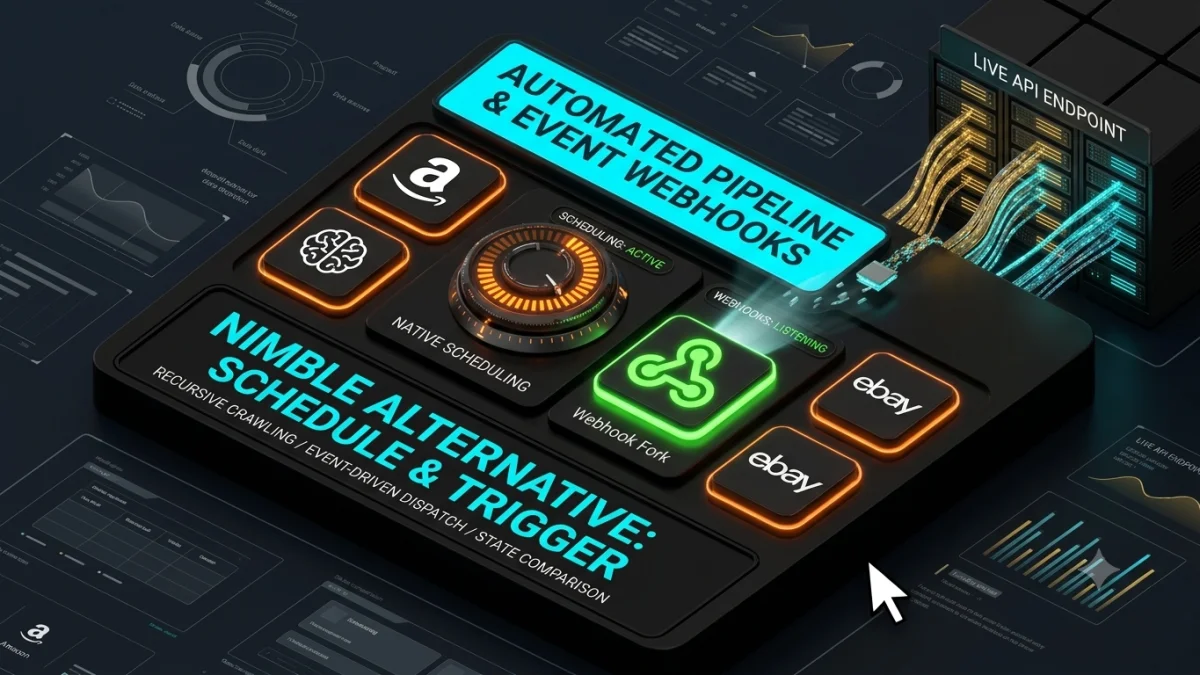
Stop wasting engineering cycles trying to build polling services. Learn how to schedule recursive web scrapes and dispatch webhook payloads automatically when data updates.
Stop feeding raw HTML dumps to your LLMs. Learn how to connect Gluedly to OpenAI and LangChain to build context-aware AI agents that run on clean, reliable data structures.
Meta goes to extreme lengths to protect its DOM. Here is how our engineering team survived weeks of "DOM archaeology" to build an experimental, login-free Facebook group scraper—and the architectural breakthroughs that made it work.
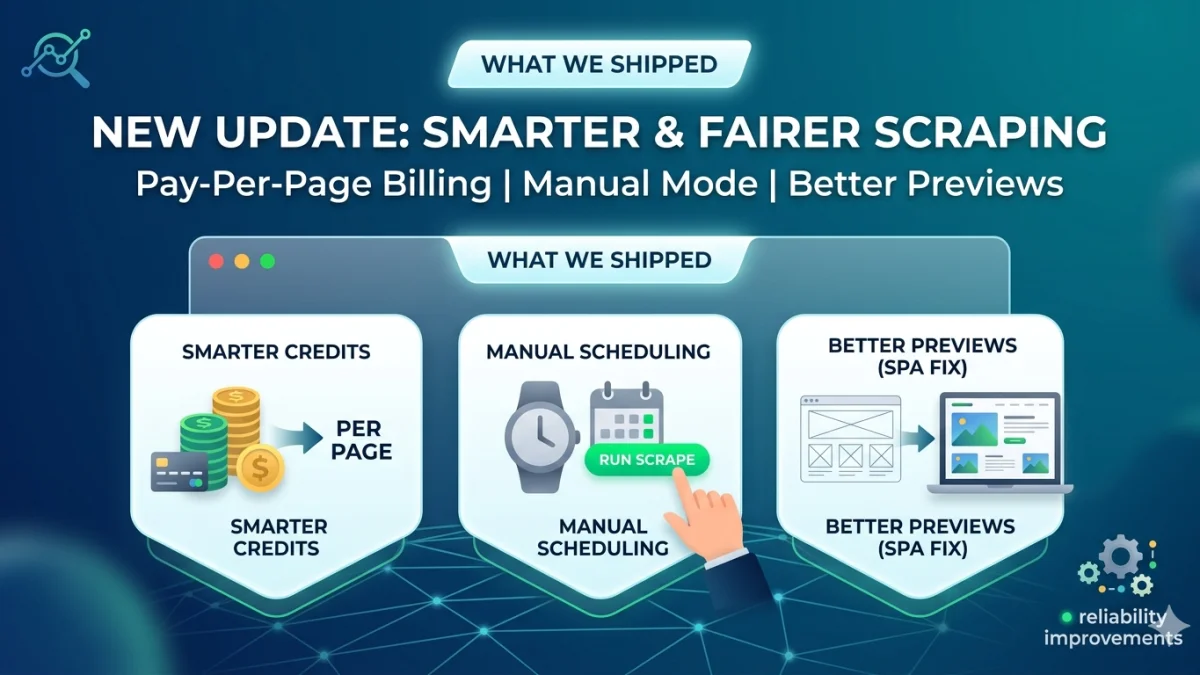
Scraping shouldn't feel like a guessing game. This week, we launched smarter, step-by-step credit checks so you only pay for the pages that actually run. Plus, we’ve added an on-demand Manual Mode to stop overnight credit drains, and upgraded our mapper so modern JavaScript sites actually load with full styling—no more broken wireframes.